Change Data Capture

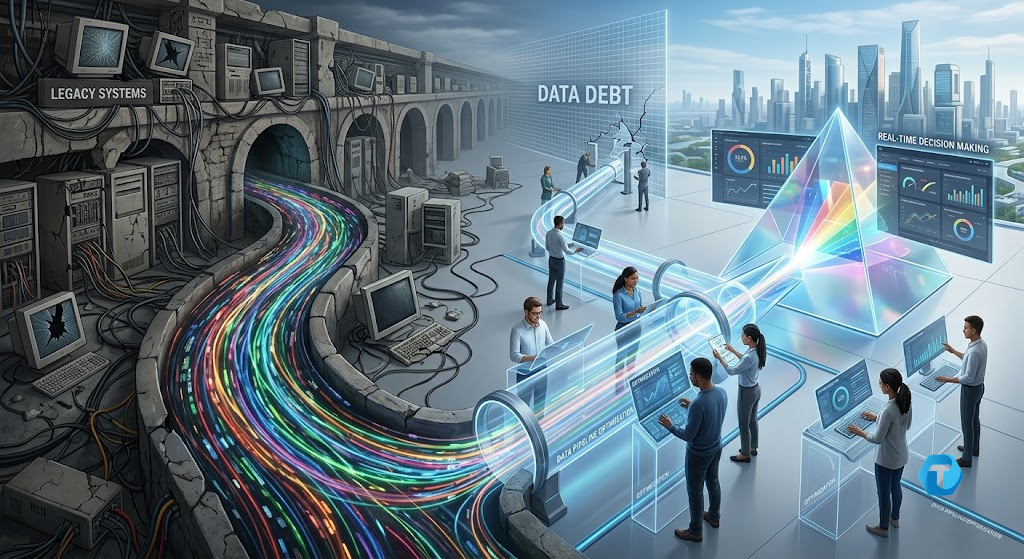
Data pipeline optimization and real-time data streaming architecture graphic
Technology & Innovation

Tackling Data Debt: A Strategic Blueprint for Data Pipeline Optimization and Real-Time Decision Making

Tackling Data Debt: A Strategic Blueprint for Data Pipeline Optimization and Real-Time Decision Making Every scaling enterprise eventually reaches a critical tipping point where its most valuable asset becomes its primary operational bottleneck. You see it in executive dashboards that take hours to refresh, cloud infrastructure invoices that balloon without explanation, and data engineering teams spending eighty percent of their week patching broken ETL scripts. This silent accumulation of architectural band-aids, shortcut queries, and unmonitored dependencies is what technical leaders call data debt. For Chief Data Officers, Lead Data Engineers, and BI Managers, data debt is not merely a backend inconvenience—it directly hampers your company’s ability to capitalize on fresh operational signals. When marketing needs immediate insights on campaign conversions, or risk management demands sub-second fraud detection, legacy batch infrastructure collapses under the pressure. Our team at Techotd frequently meets enterprise leaders whose analytics stacks were built for yesterday’s daily batch routines rather than today’s event-driven demands. Eliminating this structural drag requires a comprehensive strategy centered on data pipeline optimization—turning fragile, slow processing flows into resilient, low-latency pipelines that power confident, real-time decision making across the business. The Invisible Drag of Data Debt on Modern Engineering Teams Data debt rarely accumulates overnight during a single catastrophic project failure. Instead, it creeps into enterprise systems through dozens of everyday tactical compromises. A marketing team requests an urgent ad-hoc report, so a developer writes a quick SQL script directly against a production database. Six months later, four downstream dashboards and two financial reporting tools quietly depend on that unmonitored, undocumented script. Multiply this pattern across fifty departments and hundreds of microservices, and you inevitably end up with a tangled “spaghetti architecture” that nobody dares to touch. Historically, enterprise data infrastructure relied heavily on traditional night-time batch processing. Relational databases staged raw records, scheduled cron jobs executed heavy SQL transformations during off-peak hours, and pre-aggregated data marts served static morning reports. That model worked well when business operations moved at a daily or weekly rhythm. Today, however, business operations run continuously, and waiting twelve hours for updated inventory levels or user activity logs creates unacceptable competitive lag. When growing enterprises attempt to force legacy batch systems to support real-time demands without undertaking root-cause refactoring, several severe operational pain points surface: Pervasive Data Latency: Crucial business units are forced to make high-stakes choices using stale information. By the time supply chain anomalies, customer churn triggers, or transaction anomalies appear on executive dashboards, the opportunity to mitigate the issue has already passed. Runaway Cloud Infrastructure Costs: Unoptimized SQL transformations running on modern cloud data warehouses without proper partitioning, clustering, or materialization strategies burn through compute credits at an alarming rate. Schema Drift Instability: When upstream application teams modify database schemas without cross-team coordination, downstream pipelines fail silently. This introduces subtle errors into reporting layers and severely damages leadership’s trust in data accuracy. Engineering Fatigue and Turnover: Senior data engineers spend their time firefighting broken jobs, debugging fragile dependencies, and performing manual backfills instead of architecting innovative machine learning capabilities. A structured initiative focused on data pipeline optimization is the only sustainable path out of this cycle. By decoupling ingestion from heavy transformations and removing redundant computation paths, technical leaders can eliminate historical debt while establishing an agile, real-time analytics baseline. How It Works in Practice: Engineering a High-Throughput Real-Time Pipeline Transforming fragile legacy data flows into robust, continuous pipelines requires moving away from rigid, monolithic batch jobs toward an event-driven, decoupled processing model. When our architects at Techotd evaluate enterprise data platforms, we emphasize modularity, horizontal elasticity, and strict data contracts right at the point of ingestion. Here is how modern high-throughput architectures function in production: 1. Event-Driven Ingestion and Change Data Capture (CDC) Rather than executing resource-intensive polling queries against production transactional databases every night, modern architectures capture record changes in near-real-time. Using  and distributed streaming platforms like Apache Kafka or Redpanda, operational events—such as a completed order or an updated customer profile—are published to dedicated stream topics the moment they occur. This eliminates heavy database locks on operational systems while capturing precise audit histories. 2. Stream Processing and In-Memory Transformations As events flow into the streaming broker, distributed engines like Apache Flink or Spark Streaming transform, validate, and enrich the data on the fly. Instead of landing raw data into storage and running heavy SQL queries later, stream processors compute running aggregates—such as rolling ten-minute transaction totals or dynamic risk scoring—with sub-second latency. 3. Decoupled Storage and Materialization Layers Storage strategies must reflect how downstream applications consume information. Key-value lookups for operational applications should land in ultra-fast caches like Redis or DynamoDB, whereas long-term analytical trends belong in columnar lakehouse storage like Snowflake, BigQuery, or Databricks. Effective data pipeline optimization ensures data is converted into efficient columnar formats like Apache Parquet or Iceberg before hitting storage layers. 4. Idempotency and Pipeline Observability Continuous pipelines must tolerate network blips, late-arriving events, and schema changes without crashing. Building pipelines for idempotency guarantees that processing the exact same event multiple times yields identical final states. Furthermore, incorporating automated data observability into your data pipeline optimization strategy allows engineering teams to track end-to-end data lineage, detect schema drift instantly, and flag quality anomalies before they impact business users. +————————–+ | Operational Databases | +————————–+ | v (CDC / Debezium) +————————–+ | Apache Kafka Topics | +————————–+ | v +————————–+ | Apache Flink Stream Ops | +————————–+ | +——+——+ | | v v +———–+ +————+ | In-Mem | | Columnar | | Cache | | Lakehouse | +———–+ +————+ Strategic Impact & Measurable Value for Executive Leaders Refactoring your core data infrastructure is far more than a technical housekeeping project; it directly transforms enterprise operational economics and market agility. For Chief Data Officers and BI Managers, investing in systematic data pipeline optimization converts back-office engineering improvements into direct financial savings and strategic advantages. Consider the tangible executive value achieved through modernized pipeline architectures: Significant Infrastructure Spend Reduction: By eliminating duplicate data processing routes, optimizing query execution logic,
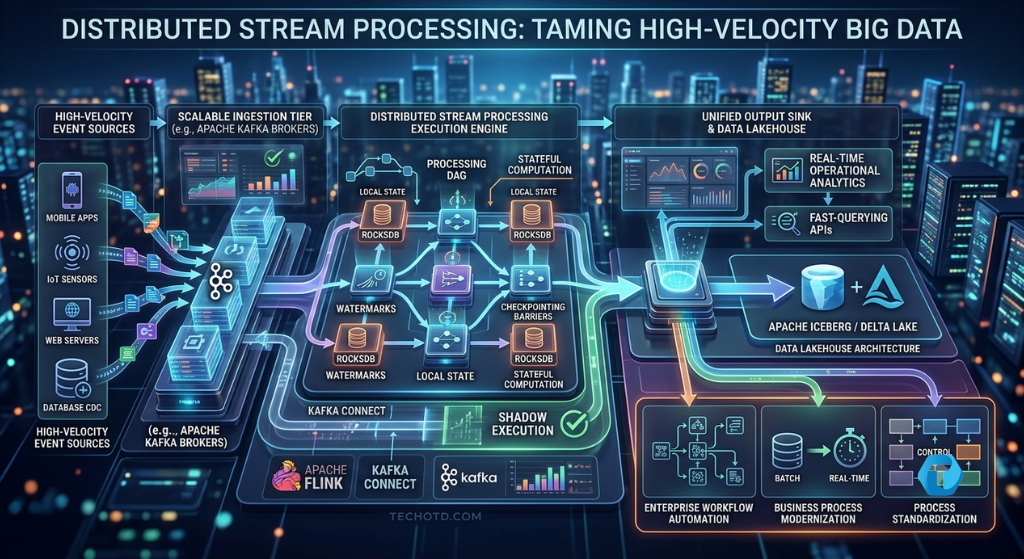
Distributed Stream Processing Architecture Diagram with Kafka and Flink
Big Data

Distributed Stream Processing Architectures: Taming High-Velocity Big Data Streams

In modern enterprise data environments, the traditional paradigm of nightly batch processing is rapidly becoming an operational liability. As business domains demand instantaneous decision-making—ranging from high-frequency fraud detection in financial clearinghouses to predictive telemetry in autonomous IoT fleets—data must be computed continuously at the moment of creation. Implementing distributed stream processing allows organizations to transition from passive historical reporting to proactive, low-latency execution engines operating on continuous data streams. Part 1: The Paradigm Shift from Batch Decoupling to Continuous Streams Historically, enterprise data architectures relied on monolithic Extract, Transform, Load (ETL) pipelines that executed on scheduled intervals. While batch systems like MapReduce or traditional SQL data warehouses served historical analytics well, they introduced a structural latency window ranging from hours to days. In high-velocity environments, this temporal delay dilutes the operational value of telemetry data. According to market intelligence from International Data Corporation (IDC), over 30% of global data generated across connected networks is real-time in nature. Furthermore, financial sector benchmark studies demonstrate that credit card fraud detection models lose up to 70% of their predictive utility if analytical scoring exceeds a 200-millisecond window. The core challenge of Big Data is no longer merely managing massive volume; it is solving for extreme velocity without compromising transactional correctness. Transitioning from static datasets to continuous event streams requires moving away from disk-bound tabular storage toward append-only log primitives. Rather than querying state that sits at rest, distributed stream processing flips the computing paradigm: queries remain persistent and long-running within memory while unbounded data flows continuously through them. Part 2: The Core Anatomy of Distributed Stream Processing To process millions of incoming events per second with sub-second response times, streaming platforms decouple ingestion, compute, and state management into specialized distributed tiers. At the ingestion boundaries, high-throughput partitioned message logs—such as Apache Kafka or Apache Pulsar—serve as the durable event bus. These brokers utilize sequential append-only disk writes to achieve multi-gigabyte ingestion speeds while providing deterministic offset management for message replays. Directly downstream sits the execution engine. Modern distributed stream processing engines utilize Directed Acyclic Graph (DAG) query planners to distribute partition-level workloads across worker clusters. Unlike stateless microservices, streaming compute nodes maintain local physical state in high-performance key-value stores (such as RocksDB embedded directly within host memory). By retaining local state buffers, stream engines eliminate the network round-trip overhead traditionally incurred when querying remote databases during event enrichment. This enables stateful compute operations—such as sliding temporal aggregations, multi-stream joins, and sessionization—to execute with microsecond locality. Part 3: Overcoming Latency, Out-of-Order Events, and State Consistency Operating a continuous compute engine across non-deterministic distributed networks presents severe architectural trade-offs, specifically regarding time domains, network jitter, and node failures. 1. Disentangling Event Time from Processing Time In distributed networks, the moment an event occurs in the physical world (Event Time) rarely aligns perfectly with the moment it arrives at the processing server (Processing Time). Network latency, device disconnects, and mobile queue backups cause messages to arrive out of order. Advanced distributed stream processing frameworks resolve this by utilizing watermarks—heuristic markers embedded into the stream stream that signal temporal completeness. Watermarks allow stateful windows to progress deterministically based on event timestamps rather than volatile wall-clock server times. 2. Guaranteeing Exactly-Once Processing Semantics In the event of hardware failures or worker crashes, stream processing systems must recover state without dropping events (at-most-once failure) or duplicating calculations (at-least-once failure). Achieving true exactly-once semantics (EOS) requires two structural synchronization mechanisms: Asynchronous Barrier Checkpointing: Based on variants of the Chandy-Lamport algorithm, lightweight snapshot barriers flow alongside data records through the DAG, persisting execution state to durable object storage without blocking pipeline throughput. Two-Phase Commit (2PC) Sink Operators: Ensuring that state writes to external sinks (such as transactional databases or storage layers) commit synchronously with the engine’s internal checkpoint offsets. Part 4: Architectural Blueprint: Integrating Kafka, Flink, and the Data Lakehouse Building a enterprise-grade real-time analytical ecosystem requires orchestrating message brokers, stream processors, and unified storage formats into a cohesive topology. A battle-tested production blueprint structures data flow across four decoupled layers: Ingestion Tier: Edge telemetry, application logs, and database Change Data Capture (CDC) streams are published to partitioned topics in Apache Kafka. Stream Processing Tier: Distributed engines like Apache Flink or Spark Structured Streaming consume topic partitions, applying windowed transformations, machine learning inference models, and real-time alerts. Speed Layer Storage: Low-latency key-value stores (such as Redis or Apache Cassandra) store the immediate results of streaming aggregations for real-time dashboarding and API querying. Unified Storage Tier: Stream sinks flush immutably transformed event logs into open table formats like Apache Iceberg or Delta Lake. This unifies streaming and batch analytics under a cohesive Data Lakehouse architecture. By deploying this decoupled topology, enterprise data teams eliminate brittle point-to-point integrations and establish a unified streaming backbone capable of serving both operational applications and offline machine learning pipelines. Key Takeaways for Distributed Stream Processing Unlocking real-time intelligence requires moving beyond ad-hoc data pipelines toward disciplined architectural patterns. Adopting scalable distributed stream processing allows engineering organizations to process unbounded event streams with mathematical correctness, guaranteeing state consistency despite cluster failures. By coupling stateful streaming compute with open table storage formats, enterprises can systematically eliminate operational latency, reduce infrastructure overhead, and drive automated decision systems at scale. Frequently Asked Questions (FAQ) What is the difference between batch processing and distributed stream processing? Batch processing executes queries on bounded, historical datasets stored at rest on fixed time schedules. In contrast, distributed stream processing executes long-running, continuous queries over unbounded event data in motion, delivering low-latency results within milliseconds of event generation. How do stateful stream processors maintain recovery during node failures? Stateful stream engines maintain internal state locally in high-performance embedded key-value stores (e.g., RocksDB) while periodically taking distributed, non-blocking snapshots using checkpoint algorithms. If a worker node crashes, the system recovers state by resetting execution offsets to the latest valid checkpoint and replaying subsequent message logs. Why is event time critical in real-time streaming pipelines? Event time reflects the exact epoch timestamp when an action occurred at

Scroll to Top